

What is cloud native architecture
Cloud native architecture is an approach to system design built specifically to run in cloud environments, leveraging elasticity, automation and geographic distribution — unlike systems that are merely "hosted" in the cloud but designed as if they were on a fixed physical server.
In an enterprise context, this means combining containers, automated orchestration, microservices and declarative infrastructure to build platforms that scale on demand, recover from failures automatically, and allow continuous delivery without downtime.
Cloud native isn't just "being in the cloud"
Migrating a monolith to an AWS VM doesn't make the system cloud native. What defines this architecture is the design: decoupling, automation, elasticity and failure resilience from the ground up.
The 12 factors and core principles
The 12-factor app methodology, created by Heroku, remains the most widely used conceptual foundation for designing cloud native applications. Some of the most relevant principles for enterprise contexts:
Externalized config
Configuration lives outside the code, in environment variables or services like Vault, never hardcoded.
Explicit dependencies
Every dependency is declared and isolated, never assumed to be present in the runtime environment.
Stateless processes
The application holds no local state; any instance can serve any request.
Horizontal scalability
Scaling means adding more process instances, not increasing resources on a single machine.
Statelessness is the most ignored prerequisite
Many teams try to adopt containers and Kubernetes without first removing local state from the application. The result is services that "look" cloud native but fail when scaled horizontally.
Containers as a packaging unit
Containers package the application together with its dependencies into an immutable, portable unit, eliminating the classic "works on my machine" problem. This standardization is the foundation on which all cloud native automation is built.
FROM node:20-alpine AS build
WORKDIR /app
COPY package*.json ./
RUN npm ci --omit=dev
COPY . .
RUN npm run build

FROM node:20-alpine
WORKDIR /app
COPY --from=build /app/dist ./dist
COPY --from=build /app/node_modules ./node_modules
ENV NODE_ENV=production
EXPOSE 3000
USER node
CMD ["node", "dist/server.js"]
Using multi-stage builds, as in the example above, reduces the final image size and removes build tooling from the production environment, shrinking the attack surface — a critical requirement in regulated enterprise environments.
Orchestration with Kubernetes
If containers solve "how to package," orchestration solves "how to operate thousands of them in production." Kubernetes has become the de facto standard for enterprise orchestration, automating deployment, scaling, self-healing and load balancing.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: checkout-service
spec:
  replicas: 3
  selector:
    matchLabels: { app: checkout }
  template:
    metadata: { labels: { app: checkout } }
    spec:
      containers:
      - name: checkout
        image: registry.wdseven.com/checkout:1.4.2
        resources:
          requests: { cpu: "250m", memory: "256Mi" }
          limits:   { cpu: "500m", memory: "512Mi" }
        readinessProbe:
          httpGet: { path: /health, port: 3000 }
          initialDelaySeconds: 5
---
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata: { name: checkout-hpa }
spec:
  scaleTargetRef: { apiVersion: apps/v1, kind: Deployment, name: checkout-service }
  minReplicas: 3
  maxReplicas: 20
  metrics:
  - type: Resource
    resource: { name: cpu, target: { type: Utilization, averageUtilization: 70 } }
This file declares not just "what" to run, but also "how" the system should react to load: between 3 and 20 replicas, scaling automatically once average CPU exceeds 70%. This is the essence of declarative infrastructure.
Does your infrastructure scale automatically?
WD Seven's Cloud & DevOps team designs enterprise Kubernetes clusters with autoscaling, observability and security from day one.
Microservices and decoupling
Microservices split a monolithic application into independent services, each responsible for a specific business domain (e.g. catalog, payments, users). This lets teams work, deploy and scale parts of the system independently.
Domain-Driven Design
Services aligned to real business domains, not arbitrary technical layers.
Asynchronous communication
Queues and events (Kafka, RabbitMQ, SQS) reduce temporal coupling between services.
Database per service
Each microservice has its own storage, avoiding coupling via a shared schema.
Microservices come with complexity cost
Prematurely splitting a system into dozens of microservices without operational maturity (observability, CI/CD, service mesh) usually creates more problems than it solves. It becomes a "distributed monolith" in disguise.
Service mesh and service-to-service communication
With dozens (or hundreds) of microservices, manually managing communication, security and observability between them becomes unfeasible. A service mesh (such as Istio or Linkerd) injects a sidecar proxy next to each service, centralizing:
Automatic mTLS
Encryption and mutual authentication across all services, without changing application code.
Retry and circuit breaking
Resilience policies applied transparently to all internal communication.
Traffic shifting
Canary releases and A/B testing controlled at the network layer, without changes to the service.
Data in distributed architectures
Distributing logic across microservices is relatively simple; distributing data with consistency is the real enterprise challenge. Essential patterns include:
Event Sourcing
System state is derived from an immutable sequence of events, enabling audit and replay.
Eventual consistency
Accepting that data across services converges with delay, in exchange for availability and performance.
Saga Pattern
Distributed transactions coordinated through a sequence of compensable steps in case of failure.
CQRS
Separation between write and read models, optimizing each path independently.
Need to modernize fragmented legacy systems?
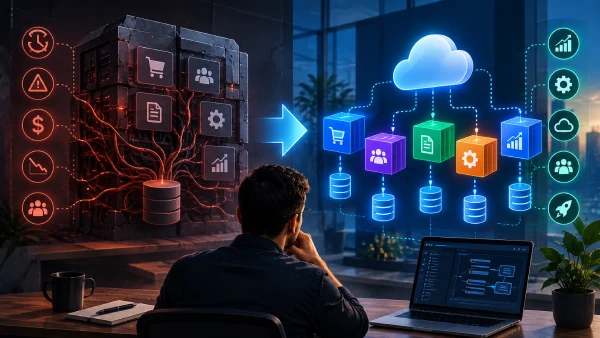
WD Seven also works on system modernization and integrations & APIs, migrating monoliths to distributed architectures safely.
Enterprise observability
In a system with dozens of microservices, debugging an issue without structured observability is practically impossible. The classic three pillars remain valid — and increasingly integrated:
Metrics
Time series (Prometheus) on latency, error rate and resource saturation.
Centralized logs
Structured aggregation (ELK, Loki) enabling correlated search across services.
Distributed tracing
Tracking (Jaeger, OpenTelemetry) a request across multiple services.
Security: Zero Trust and DevSecOps
Distributed architectures expand the attack surface: every service, API and communication channel is a potential vulnerability point. The Zero Trust model assumes no request is trusted by default, even inside the internal network.
mTLS between all internal services
Vulnerability scanning of container images
Centralized secrets management (Vault, KMS)
Restrictive network policies by default
Pipeline with automated security tests (DevSecOps)
Security as code
In mature enterprise architectures, security policies are versioned and tested alongside application code — not applied manually after deployment.
CI/CD and GitOps
Delivery speed is one of the main gains of cloud native architecture — but it only holds up with mature pipelines. The GitOps model treats the Git repository as the single source of truth for infrastructure state.
Commit to the repository
A code change or declarative manifest is versioned in Git.
CI pipeline
Automated tests, image build and security scans are executed.
GitOps synchronization
An operator (ArgoCD, Flux) detects the change and applies it automatically to the cluster.
Validation and automatic rollback
Post-deploy metrics are monitored; deviations trigger a rollback with no manual intervention.
Are your deployments safe and automated?
WD Seven builds complete CI/CD and GitOps pipelines as part of the Cloud & DevOps service, reducing risk in every release.
Monolith vs. cloud native: comparison
| Aspect | Traditional monolith | Cloud native enterprise |
|---|---|---|
| Scalability | Vertical, limited | Horizontal, nearly unlimited |
| Deployment | All-or-nothing, maintenance windows | Independent per service, zero downtime |
| Failure resilience | A single module failure brings everything down | Failure isolation per service |
| Operational complexity | Low | High (requires DevOps maturity) |
| Delivery speed | Slows down as the system grows | Parallel teams deliver independently |
Not every company needs "full" cloud native
For lower-criticality systems, a well-modularized monolith (modular monolith) can be more efficient than premature microservices. The decision should be guided by real scale, not market trends.
Cloud native maturity checklist
Stateless applications configurable via environment
Standardized containerization with minimal, secure images
Orchestration with autoscaling and configured health checks
Observability with correlated metrics, logs and tracing
Zero Trust security with mTLS and centralized secrets management
CI/CD pipeline with GitOps and automatic rollback
Conclusion
Cloud native enterprise architecture isn't a list of tools (Kubernetes, Istio, Kafka), but a set of design principles: decoupling, automation, observability and resilience from the ground up. Adopting these tools without internalizing the principles results in complexity without the real benefits of the cloud.
The ideal path is evolutionary: validate statelessness and containerization first, then move toward orchestration, microservices and service mesh as business scale justifies the operational complexity investment.
Containers
Standardized, portable packaging.
Orchestration
Automation of deployment, scaling and recovery.
Observability
Full visibility into the distributed system.
Security
Zero Trust applied from the architecture up.
Want to assess your platform's cloud native maturity?
Our strategic consulting team analyzes your current architecture and designs a realistic evolution roadmap.